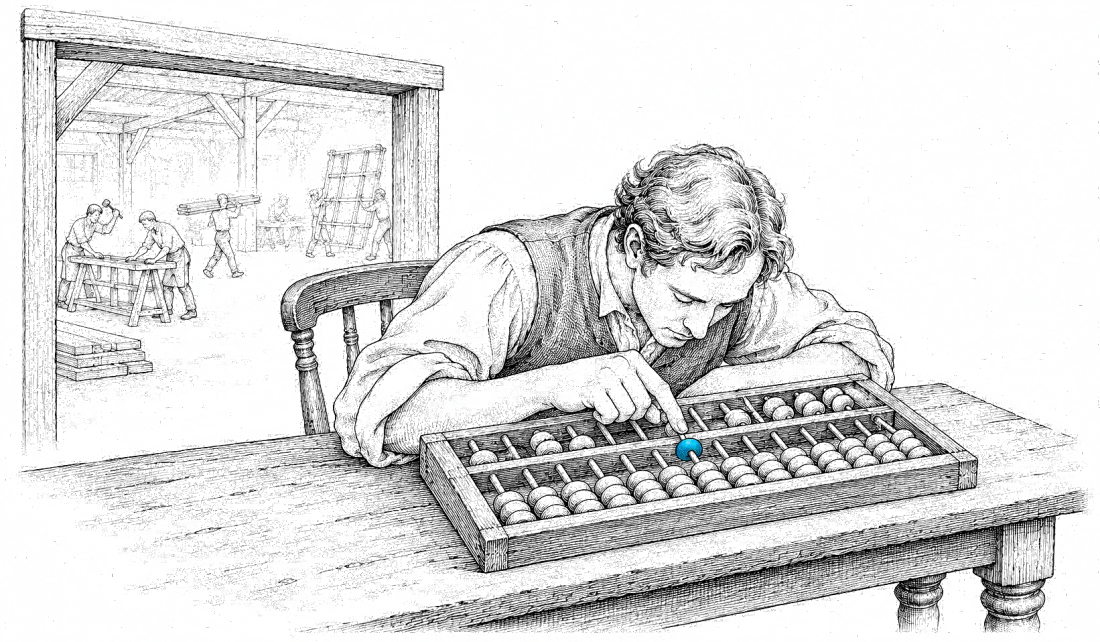
In Oscar Wilde's Lady Windermere's Fan, a cynic is someone who knows the price of everything and the value of nothing. By that standard, most AI cost tooling is deeply cynical.
It will tell you, to the token, what you spent last month. With a bit of effort, it will tell you which team spent it, on which model, through which agent. What it can't tell you is whether any of it was worth it.
This is accounting in the oldest sense: an abacus with a nicer UI. Counting beads matters, and you can't manage what you can't measure. But measuring isn't understanding, and understanding isn't improving. As agents take on more of the work, the gap between the three is where the money goes.
Count: what did you spend?
The first rung is counting: how many tokens, how many dollars, over what period. Every provider console does this, and most AI cost dashboards are built on it.
It is necessary, and it is largely retrospective. A metering view tells you the bill went up 40% last month. It cannot tell you whether that bought you 40% more work, 400% more work, or an agent that spent the month arguing with itself.
Sort: who spent it, and on what?
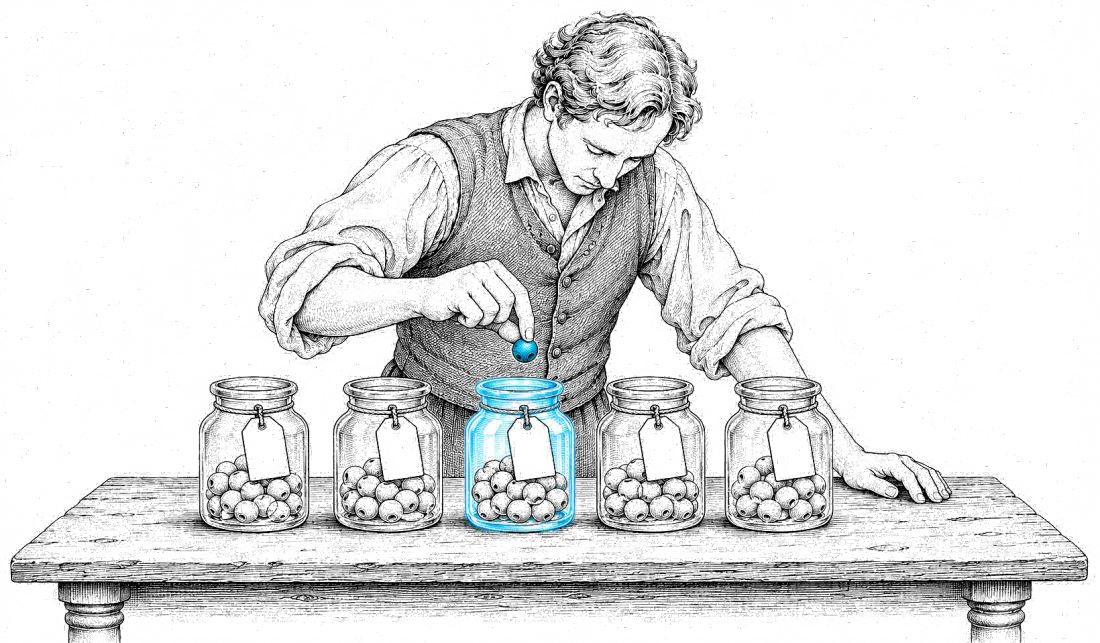
The second rung is sorting: attributing spend by agent, model, user and team, and increasingly by what the work actually was. This is a real step up. It turns a single number into a map, and a map tells you where to look.
But a map is not a diagnosis. A team whose agents account for a third of spend might be doing the most valuable work in the company, or re-reading the same monorepo forty times a day.
Sorting the beads by color is still counting beads.
Analyze: why did it cost that?
The third rung is analysis, and it is harder: why a given piece of work cost what it did.
That question can only be answered at the level of the trajectory: the sequence of model calls, tool calls and context an agent assembled to get from task to result. Look at enough trajectories and the waste stops looking random. It falls into familiar patterns:
- Re-reading. Agents pulling the same files, docs or tool outputs into context again and again, because nothing told them they already had it.
- Dead ends and retries. Exploration that goes nowhere, failed tool calls retried verbatim, loops that only end when a budget runs out.
- Context bloat. Verbose tool output stuffed into the window, then dragged along for every subsequent call.
- Cache misses. Reusable context that misses the cache because entries expire, prefixes change, or requests aren't structured to reuse it.
- Compaction churn. Long sessions that summarize, forget, and then go back and rediscover what they just summarized away.
- The wrong model. A frontier model doing work a smaller one might handle just as well, and only testing against the same outcomes will tell you.
- The wrong playbook. A generic approach that doesn't suit the codebase or the task: working serially where parallel tool calls would do, or dragging a whole investigation through one context when a sub-agent could explore and report back just the answer.
src/billing/$2.20src/billing/ again$2.00As I argued in Amnesia Is Expensive, much of this is structural rather than a bad prompt here or there, and none of it is visible on a spend dashboard.
Some reporting tools are starting to reach this rung, sampling sessions to flag friction, rework and skills worth building. But knowing where the friction is doesn't remove it.
Align: spend where it matters
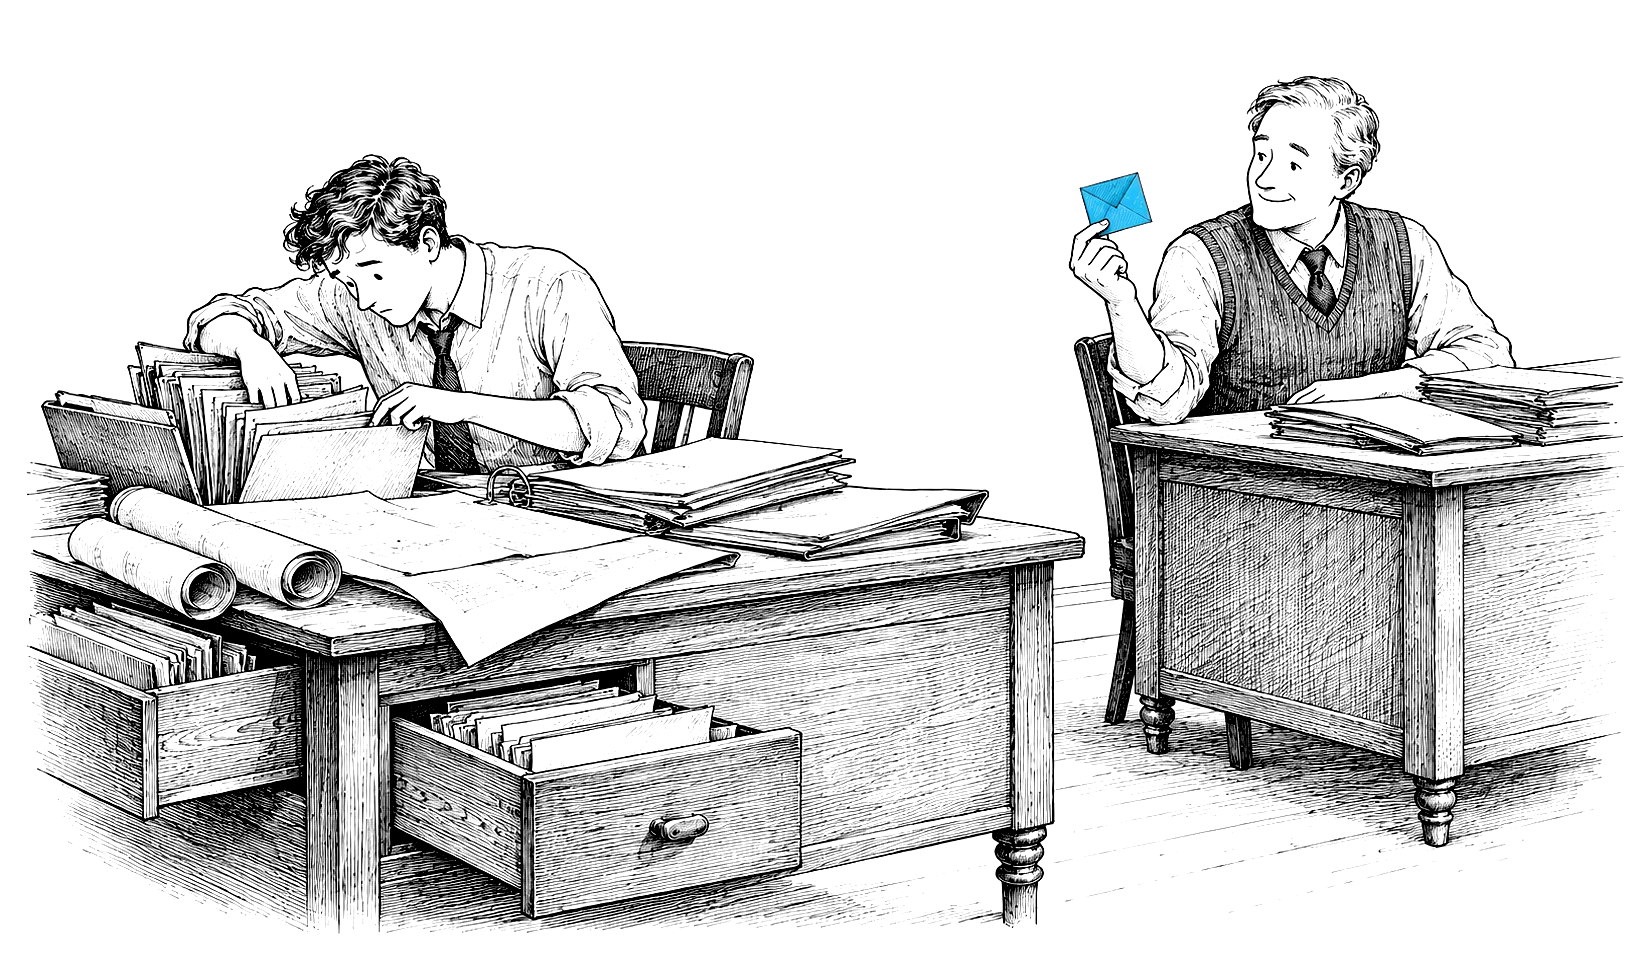
Count, Sort and Analyze each give you a better answer than the last. But every one of them, however smart, ends in a report. And a report is not an action.
Value comes from changing something: where the spend goes, or how the work gets done. There are two ways to do that.
The first is to align. With a clear picture of what the work is and what it costs, people can steer: set budgets that track priorities, default routine work to the right model, write guidelines for how agents should be used, and invest more where the return is clear.
A cheap failed task isn't good value, and an expensive successful one isn't necessarily bad value. The question is whether the expenditure was justified by the result.
This is where most reporting leads, and it matters. But it works at the level of teams and quarters, not individual trajectories.
Streamline: stop paying for the same work ad nauseam
The second is to streamline: change what the agents actually do. For any piece of work, ask three questions. Could it have been done cheaper? Could it have been done faster? Could it have been done better? The old engineering joke says pick two. With agents, waste tends to cost you all three, so removing it often improves all three. That is what Token IQ is built to answer, and to act on: look inside the trajectories, find where expenditure isn't advancing the task, and remove it.
Knowing an agent re-reads the same context forty times is only interesting if something then stops it doing so. That might mean giving the agent a durable summary of what it keeps relearning, restructuring context so caches actually hit, or turning a procedure it keeps re-deriving into a reusable skill.
The best of these fixes compound. What one agent learns about a repository, such as how it's laid out, which commands work, and which approaches lead nowhere, should carry over to the next agent on a different task tomorrow, rather than being paid for all over again.
Keep measuring, because a skill is not one and done. The codebase it was distilled from keeps changing. The models keep evolving, and what one needed spelled out the next may do unprompted, or differently. The harness running the agent shifts underneath it too. A skill that saved tokens last month can quietly go stale, or start steering the agent wrong. Optimization has to be a loop: observe, distill, verify, and refresh as the ground moves.
A smaller bill is not the only goal
It's tempting to read all this as a cost-cutting story. It isn't, quite.
The easiest way to shrink an AI bill is to have your agents do less. Cap the budgets, throttle the usage, push everyone onto the cheapest model. The number goes down, and so does the work. That is the abacus answer: it optimizes the only thing it can see.
The goal is more useful work for every token you spend, which sometimes means spending more, on the right things. You can't get there by counting. You get there by understanding what your agents are actually doing, and having the means to make them do it better.
- Count and Sort. Cost tooling tells you what was spent and by whom. It can't tell you whether it was worth it.
- Analyze. Why work cost what it did is only visible in the trajectories: re-reading, retries, context bloat, cache misses, compaction churn, the wrong model or playbook.
- Align and Streamline. Every report stops short of an action. Value comes from changing where the spend goes, or what the agents actually do.
- The goal. More useful work for every token, which sometimes means spending more on the right things.
Know the price of everything, by all means.
Just don't stop there.
 {{ b.brand }}
 Classie