The price of intelligence is falling. The cost of using it is another matter.
Models are getting cheaper, context windows are getting longer, and agents are taking on more complex work. But a cheaper token doesn't necessarily make a cheaper task. An agent can get through millions of tokens navigating repositories, reconstructing context, retrying approaches that already failed and revisiting decisions it made earlier.
Some of that work is necessary, and some of it is productive exploration. Some is simply waste, and most organizations can't tell which is which.
Finance sees the bill, perhaps broken down by model, provider or team. What the bill doesn't show is what the agents actually did, why they did it, or whether the work was worth what it cost.
We would never manage people this way. Nobody judges an engineer from the payroll report. You look at what they shipped, how they got there, and how much of the week went on work somebody had already done, or work nobody asked for. Agents behave a lot more like people than like software, a point our CEO Poonacha Kongetira made on Truth in IT this summer, and the comparison holds for cost as well as for risk.
What are we actually paying for?
One Claude Code session in our own telemetry ran across three days: $552, 195 prompts driving nearly 2,000 model calls, and 926 million tokens. The agent was active for fourteen and a half hours, the human for thirty-seven minutes. It was productive, too, with sixty commits and nineteen pull requests to show for it. But $458 of that $552 went on the model re-reading context it had already seen.
Was $552 expensive? Probably not: next to the engineering hours behind sixty commits, it's cheap. Was it inefficient? Possibly, but the numbers alone can't say. What matters is how much of the work the agent didn't need to do, and the bill doesn't show that.
To understand efficiency, we need to know what the agent was trying to accomplish, which repositories it touched, where it spent its time, how much context it carried, and how much of the work it repeated.
The unit of analysis cannot simply be the request. It has to be the workflow, and ultimately the organization.
Amnesia, billed by the token
Anyone who has watched a coding agent at work will recognize this. It explores a directory tree it visited yesterday and reads a handful of files to rediscover a naming convention that hasn't changed in months. It works out the test command from the package manifest. It tries an ORM pattern the team abandoned, fails, reads the migration history, and eventually lands on the approach a colleague could have explained in four words.
Then the next session starts, whether it's the same developer tomorrow or a colleague down the hall, and the whole thing begins again.
Picture a new hire who turns up every morning having forgotten everything from the day before. They're bright and they get there in the end, but the first hour of each day goes on relearning where things live, and nobody thought to leave them a note. The model is rarely the problem in that story. What's missing is the context, kept from one session and handed to the next.
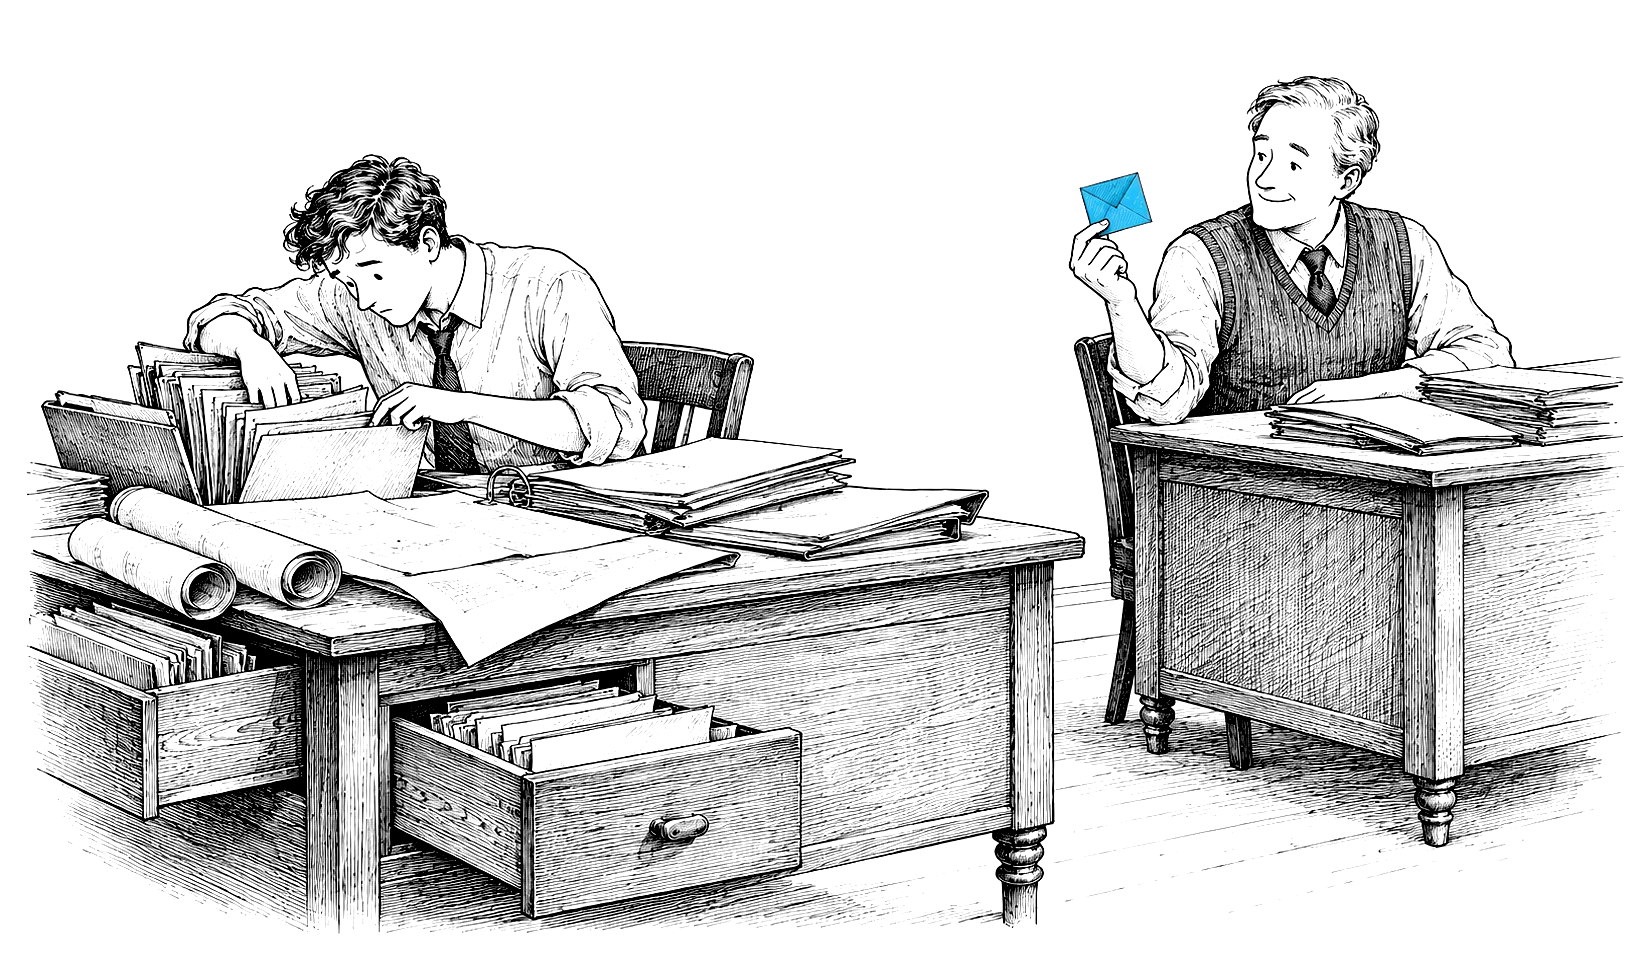
A developer may watch an agent find its way around a repository perfectly well, without knowing that five other agents worked out the same conventions earlier that week. Token accounting can't show that. To see it, you have to follow agent behavior across sessions, developers, repositories and workflows.
What the traces reveal
At Classie, we instrument agent activity so that consumption can be tied to behavior and intent. That covers the obvious questions, such as which models are used, by whom, against which repositories and at what cost. It also covers what agents were asked to do, which tools and files they touched (and whether they should have), where the tokens went and what work they repeated.
That is the idea behind Token IQ: looking past total consumption to how tokens are actually used, where the waste comes from and what could be done about it.
In our own repository, we gave a coding agent a ticket that touched five services. Left to itself, it spent most of its effort exploring, navigating and backtracking before it got to the implementation.
From the telemetry Classie captured on those runs, we generated a reusable skill for that kind of task in that repository. It didn't hold the answer to the ticket. It held what you'd write down for a new team member: the service layout, the commands that matter, the conventions, and the patterns that worked. The coding agent picks it up on its own.
Generic skills circulating online are written from assumptions and general good practice. This one is built on evidence: what agents actually did in this repository, where they wasted effort, and what got the job done.
The skill cut cost by three quarters on the same task, and by around 40% on related work it had never seen. Same model, same outcome: every run, with or without the skill, passed the same acceptance tests.
That is the difference between reporting cost and acting on it. A bill tells you what you spent. A trace shows where the waste is, lets you fix it, and tells you what the fix was worth.
The agent did not need less intelligence. It needed less unnecessary work.
The skills you have, and the skills you use
Generating skills is only half the job. Left alone, they sprawl like any shared knowledge: written once, copied between repositories, rarely updated and seldom retired.
Most companies have an onboarding wiki that half the team has never opened. Skills go the same way, or worse. Some are never used. Some overlap or contradict each other. Some are simply out of date, and a skill that still recommends the retired ORM models can be worse than none, because every agent that loads it heads down a path that has to be undone.
Classie shows which skills are installed, who uses them, and what they do to cost and outcome. That's how you find the ones to fix, merge or retire, and the ones worth spreading. A well-designed skill, as section 03 showed, removes far more work than it adds.
The important distinction is between installed, used and effective. Connecting skill usage to token consumption and agent behavior shows whether reusable context is earning its place.
The economics of supervision
Which brings us back to people. A good manager doesn't keep one view of how productive someone is and a separate view of how they conduct themselves. Both come from paying attention to the same work. Agents are no different, and the visibility you need to understand their efficiency is very close to the visibility you need to supervise their behavior.
A trace that shows repeated repository exploration may reveal wasted tokens. It may also show an agent reading files outside its intended scope, or calling tools that have nothing to do with the task.
- Listed the services directory
- Read 14 files to find the naming conventionCost. Five other sessions did this earlier in the week.
- Worked out the test command from the package manifest
- Read .env.productionConduct. Production secrets, nothing to do with a docs fix.
- Edited the README
Skills raise the same two concerns. A redundant skill wastes context and tokens. A poorly designed one, or a malicious one, can steer an agent toward tools, permissions or data it shouldn't be using.
These are different questions about the same underlying activity.
That is why Classie brings discovery, analysis and supervision together. Understanding agent behavior is the foundation for spending well and for governing well. A cheaper model doesn't necessarily produce a cheaper task, and a cheaper task isn't necessarily a better outcome. Cost has to be understood alongside intent, execution, quality and risk.