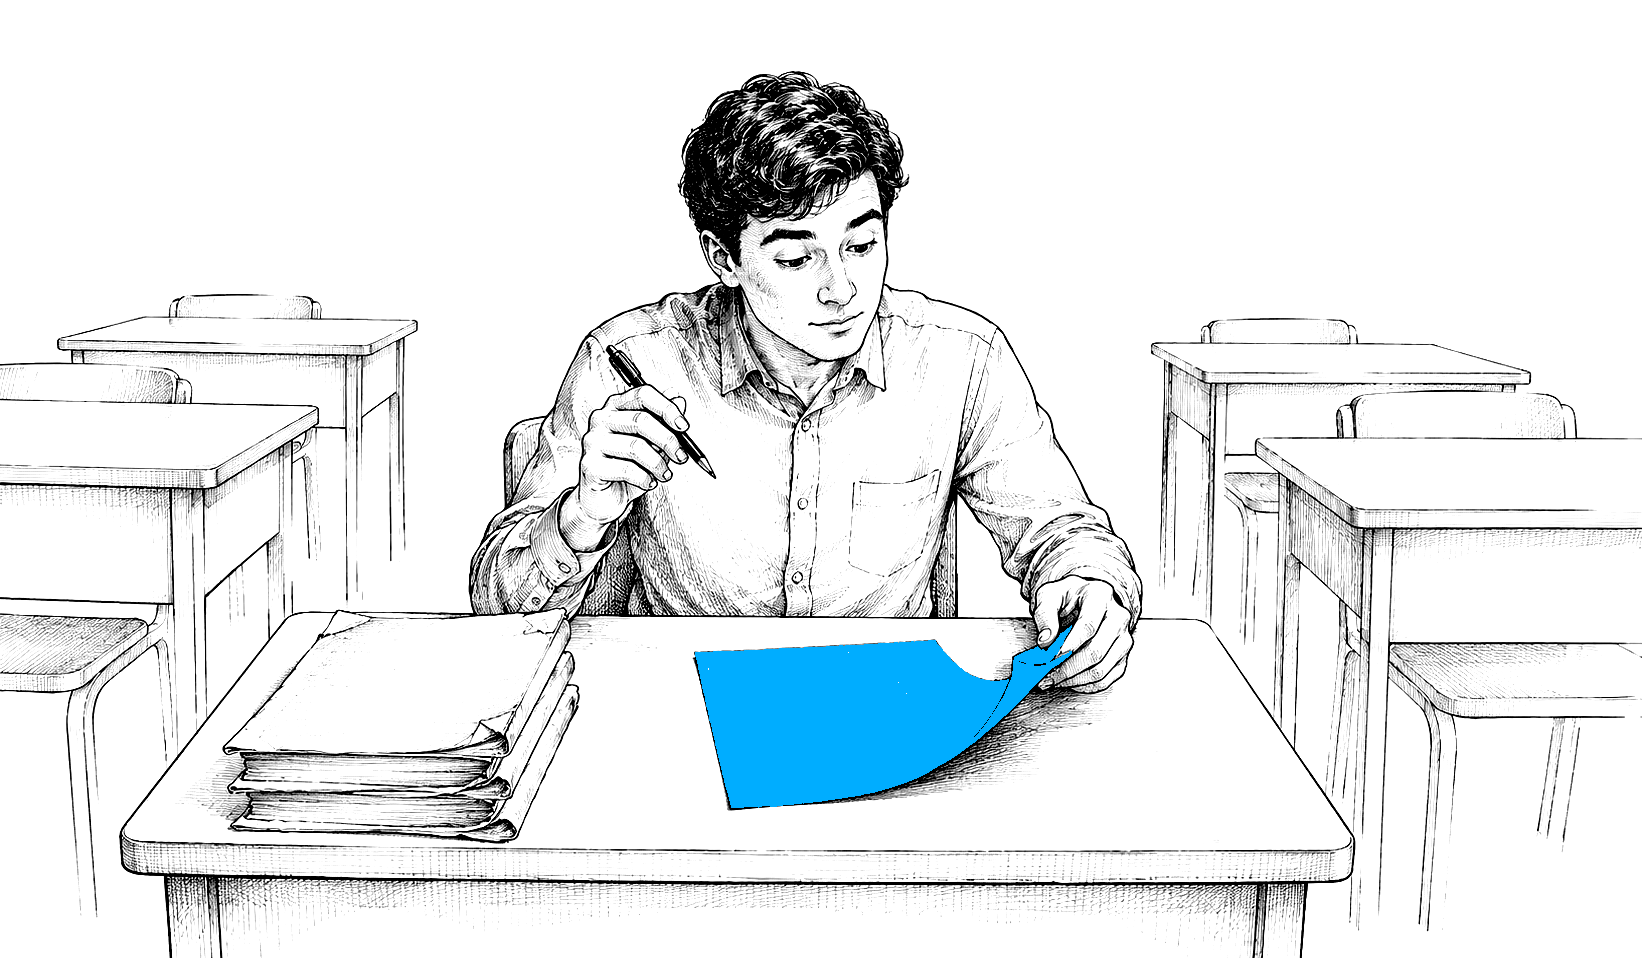
Back-to-school season brings a familiar ritual: the syllabus, the past papers, the mocks and the answer keys that come with them. You find the weak spots. You sit another paper, and another, until the scores stop moving because there is very little left to get wrong.
Then you sit the real thing. Same subject, same student, different paper. The questions are framed in a way you have not seen before, the topic you skimmed because it never came up takes half the marks, and two ideas you knew perfectly well on their own turn up welded together in question four. (I revised for my maths A-level by working through a decade of past papers. The examiners had clearly read them too, and gone somewhere else.)
You prepared well. Almost nobody scores 100 percent.
Mocks are still how you find out what you do not know, and no serious student skips them. But nobody walks into the hall believing the mock score is the result.
A mock tells you how you performed under the conditions of the mock. The exam is the first time anyone finds out how you perform under the conditions that actually occur.
Pre-deployment evals are mock exams.
An eval is evidence, not control
Serious teams now test models and agents before anything ships. Does it follow instructions? Does it refuse when it should? Does it retrieve the right context, and does it reach for the sanctioned tool rather than doing the work in its head? That is real progress. I want more of it: harder adversarial cases, and environments messy enough to resemble the ones the agent will actually work in.
Once the thresholds are met and the sign-off is collected, the system gets treated as safe. That is a bigger claim than the score can support.
Every eval has a boundary drawn around it. The prompts are fixed, or sampled from a fixed distribution, and the tools, the data and the permissions are whatever you chose to hand the harness. The score is an honest statement about what happens inside that boundary. Production does not stay inside it.
Production changes the test
For an agent, a good part of the system is assembled at runtime. Tools appear, or get quietly swapped for a wrapper somebody wrote on Tuesday. Permissions widen because widening them unblocked a launch. Credentials differ by session and by user. Retrieved documents carry text that nobody wrote for your eval and nobody read before it landed in the context window.
The model can be identical and the code unchanged. The system you are running can still not be the system you evaluated.
What the score covers
Prompts you wrote, tools you connected, documents you curated, permissions the harness was given. One configuration, held still long enough to measure.
What the day brings
Users you did not model, a tool added last week, a document shared too widely, a token nobody narrowed, and configurations that did not exist when the suite ran.
Production is less forgiving than the analogy suggests. A real exam does not hand the student a new textbook in the middle of question three. An agent's environment can change while it is running.
You can test the pattern, but you cannot enumerate every live configuration.
Safe capabilities, unsafe chain
Reading a support ticket is safe, so is looking up the customer record attached to it, and so is issuing a credit below fifty dollars. Each of those passes its own evals, and each of them should.
Run them in one session and the arithmetic changes.
Untrusted text in the ticket steers the retrieval, the retrieval crosses into an account the requester has nothing to do with, and the credit is then issued, correctly, with a valid credential, against the wrong customer. Nothing malfunctioned along the way, and every step was permitted.
Every capability looked reasonable in isolation. The danger only exists in the chain. The risk lives in the interaction between this input, this identity, this retrieved document, these permissions and this action, in one live session. Evals can test the class of failure. Runtime supervision has to govern the instance.

Supervision is the proctor, not another mock
Runtime supervision acts on the live event rather than on a sample of possible ones.
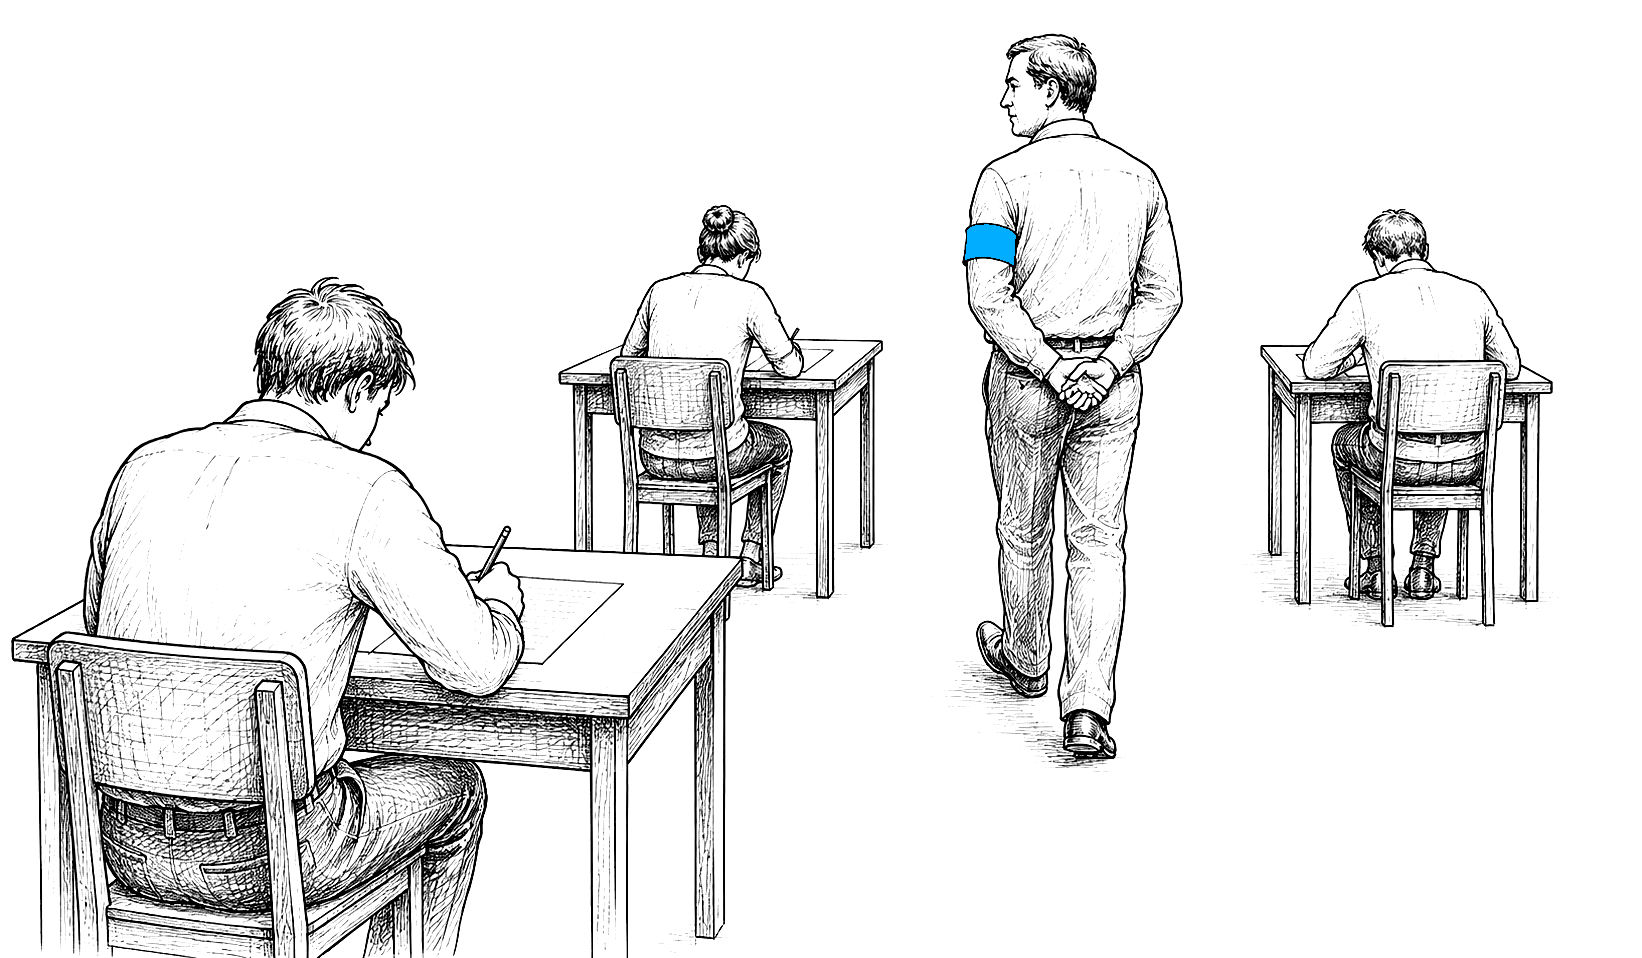
The invigilator at the front of the hall, or the proctor, depending on which side of the Atlantic you sat your exams, has not read the paper and has no intention of reading it. That is rather the point. The rules hold whatever the questions turn out to be: the person sitting the exam is the person registered for it, the phone stays in the bag, and nobody's answers become anybody else's.
Supervision works the same way. Whatever prompt arrives, whatever tools happen to be connected that morning, some things stay true.
- An agent does not cross a tenant boundary.
- Text an agent retrieved cannot enlarge what that agent is allowed to do.
- A tool discovered at runtime is not trusted because it was discovered.
- An action with real consequences waits for a human when policy says it should.
Supervision can hold those lines before the action completes. Logging never could. A log is a very good account of an incident you can no longer prevent. Supervision sees the action forming, applies the policy, and can intervene before the money moves.
Without enforcement, you are only watching.
What that buys is agents that can act with more freedom than a human-approves-everything workflow allows, without the organization losing its grip on what they do with it.
Close the loop
None of this makes evals less important. They are how you find brittleness, and how you spot the tool combinations that should never have been allowed near each other in one workflow. Production then pays it back: a blocked action becomes a test case, a near miss becomes an adversarial scenario, and an unexpected tool combination becomes a regression test. NIST and others have landed on the same advice: evaluate before deployment, then monitor and govern what happens in production.
So run the mocks, and make them harder. Evaluate the whole workflow rather than the model on its own.
Then be honest about what changes on the day. The system meets users you did not model, data you did not curate, tools that were not connected when the suite ran, and permissions that have moved since. That is the moment the evals need company.
Evals tell you whether the system is fit to walk into the room. Supervision governs what it does once it is inside.
You can ace the mock and still miss on the day.
This is the gap we built Classie for. Know what agents are actually running, what authority they are quietly holding, and govern the consequential actions while the consequence is still hypothetical.